

Cloning Ahrefs or SEMrush by scaling a single general-purpose web crawler is the mistake that burns six figures on proxies and still leaves the product with no keyword volume, no backlink velocity, and no rank history. Those three live in different subsystems with different data origins.
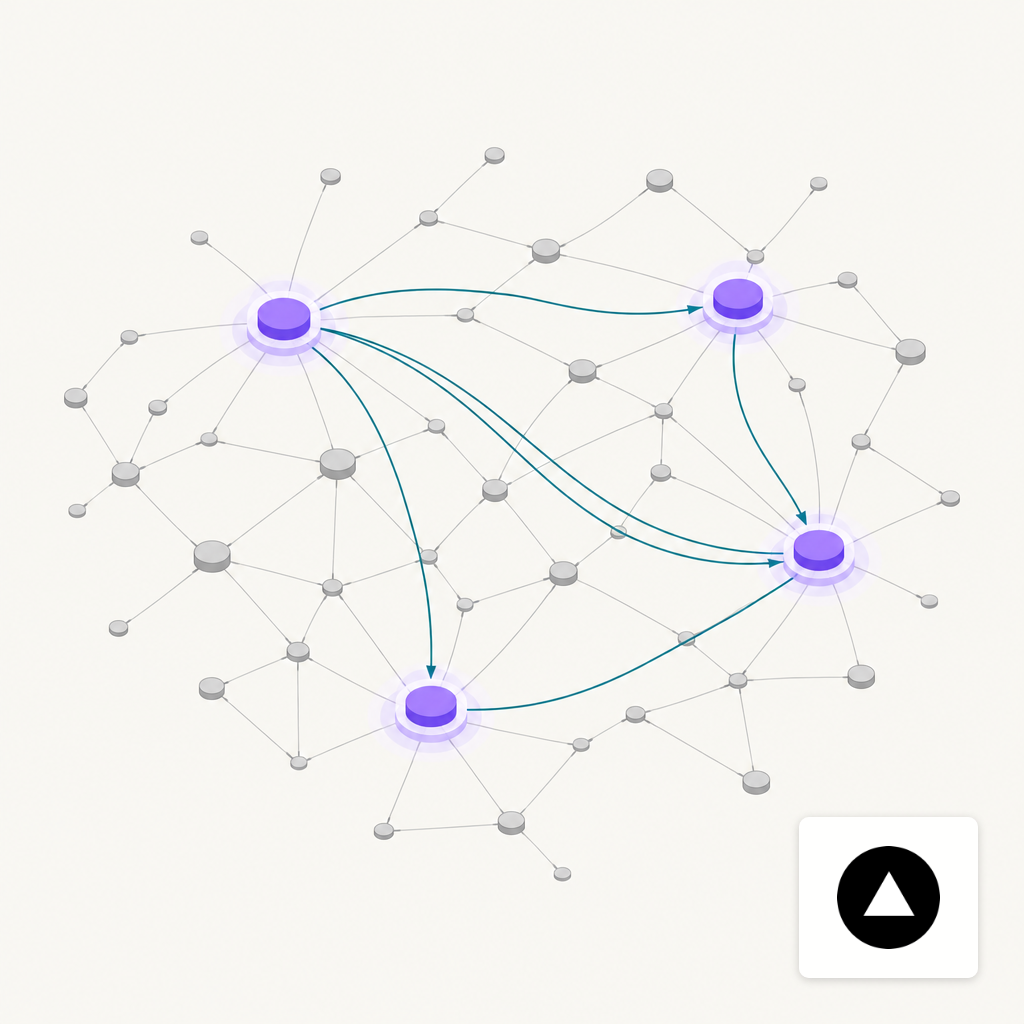
A client-facing SEO platform is four pipelines: SERP index, backlink graph, keyword universe, and site auditor. Two of them are cheaper to license than to crawl; two are cheaper to build. MCP servers glue the four into one agent-callable surface.
The Four Subsystems and Where the Money Goes
Ahrefs and SEMrush look like single products but function as four separate data factories. The SERP index tracks keyword positions over time by polling Google. The backlink graph is a compressed snapshot of the live web pointing at every domain. The keyword universe estimates search volume and intent per query. The site auditor crawls one client domain at a time for technical issues.
Costs do not distribute evenly. A backlink graph of 20 trillion edges runs tens of thousands per month in storage and compute. A SERP index polling one million keywords daily runs tens of thousands in proxy spend. Keyword inference and audit crawls are roughly an order of magnitude cheaper. The pipeline comparison of Ahrefs and SEMrush covers how the incumbents allocate; the construction picture below covers what a clone pays instead.
SERP Index: Proxy Rotation or Licensed API
Two paths cover proxy-based SERP scraping at scale. The first is residential IP rotation through a provider with roughly 10 million exit nodes, routed through a headless browser that handles CAPTCHA fallbacks. Per-query cost sits between $0.0005 and $0.002 depending on country and SERP depth. One million daily keywords runs $500 to $2,000 per day of raw bandwidth before storage.
The second path is a licensed SERP API that wraps the first path on your behalf: SerpAPI, DataForSEO, Zenserp. Per-query cost is $0.001 to $0.003 and comes back as normalized JSON. For under 500,000 queries per day, licensing is cheaper than building. Above that, building wins on marginal cost but requires a dedicated team watching layout drift.
Legal exposure sits with the scraper, not the vendor. The Ninth Circuit's 2022 opinion in hiQ v. LinkedIn allowed public-profile scraping on CFAA grounds, but the district court later entered $500,000 against hiQ on the breach-of-contract claim. Public data is not contract-free data.
Backlink Graph: License the Index, Harvest the Freshness
Cloning a backlink graph from zero rarely pencils out. The anchor is Common Crawl, which publishes an archive each month on S3. Processing its edge list into a graph store is a Spark job that fits on a few hundred cores for a day; the data itself is a network egress charge.
Freshness is where a clone earns its name. Common Crawl is a monthly batch while commercial backlink indexes refresh on a continuous rolling window. A credible clone combines Common Crawl as cold storage with a continuous crawl of 10 to 50 million priority domains, prioritized by referring-domain count against the Netcraft web server survey, which counts 1.49 billion sites across 305 million domains. The pipeline writes new edges to a graph store such as JanusGraph or TigerGraph on an hourly cadence.
Keyword Universe: Clickstream, Suggest APIs, and GSC
Keyword volume cannot be scraped directly. It is inferred from clickstream panels (Similarweb, Datos), from Google Autosuggest expansion against a seed list, and from Search Console data that users donate when they connect accounts. A keyword universe clone licenses one clickstream feed, expands seeds through Suggest, and classifies intent with an embedding model.
Zero-click behavior now dominates the query mix. A Pew field experiment found that AI Overviews cut organic clicks by 38% on triggered queries, pushing zero-click rates from 54% to 72% on that subset. A keyword universe that reports only "search volume" without an AI-triggered flag undersells the real distribution.
Search Console remains the one free source at meaningful scale, and its rate limits shape how often a multi-tenant clone can refresh per-site data.
| Endpoint | QPM per site | QPM per user | Daily per site |
|---|---|---|---|
| Search Analytics | 1,200 | 1,200 | no cap |
| URL Inspection | 600 | no cap | 2,000 |
Site Auditor: The Only Pure Build
The audit subsystem is the simplest of the four. It is a controlled crawler aimed at one client domain at a time, parsing HTML, measuring Core Web Vitals, and checking directives against the robots.txt specification. Nothing is licensed; nothing rotates residential proxies. A single Playwright worker pool clears roughly 100,000 URLs per hour per node and writes findings into the same vector store the keyword classifier uses.
Build-vs-buy favors build here because the output is per-tenant and private. Audit data that lives in a vendor silo cannot be joined cleanly to internal analytics or to the other three subsystems.
Wrapping Pipelines in MCP Servers
Each of the four subsystems is exposed as an MCP server with a typed tool surface: serp.lookup, backlinks.referring_domains, keywords.expand, audit.crawl. Agents request data by name, the MCP server routes to the underlying pipeline, and results return as structured JSON. The search.co multi-agent runner uses this pattern, with bring-your-own-key routing sending inference to the cheapest acceptable model per call.
Routing matters at the tool layer, not only the LLM layer. A serp.lookup that falls through from a residential proxy pool to a licensed SERP API on 429 errors absorbs incident load without agent code changes. The cost math on multi-provider routing translates directly to MCP tool routing: cheapest-adequate first, premium on retry, log the fallback for billing.
What Changes Over the Next Year
Two shifts move the build-vs-buy line. The first is LLM referrer traffic: ChatGPT crossed 1.2 billion weekly users in September 2026, and citation share now rivals SERP position as a tracked metric. A clone that indexes only Google SERPs is already partial, as the breakdown of rank tracking in AI search sets out.
The second is anti-scraping enforcement. Default-deny AI bot policies at CDN layer and tighter terms-of-service clauses from major publishers push the backlink graph toward licensed sources and away from self-sourced ones. Over the next year the economics tilt further toward licensing the backlink index and spending differentiation budget on the SERP, keyword, and audit layers where product teams still have room to compete on signal quality.
Written by
Samuel EdwardsSamuel Edwards is the Chief Marketing Officer at DEV.co , SEO.co , and Marketer.co , where he oversees all aspects of brand strategy, performance marketing, and cross-channel campaign execution. With 15+ years of experience in digital advertising, SEO, and conversion optimization, Samuel leads a data-driven team focused on generating measurable growth for clients across industries.